Rethinking Fashion Returns Through AI-Based Visual Inspection – Project Learning Blog

9

October

2026

No ratings yet.

1 Student Role and Contribution

My contribution to the AI Strategy was primarily centred on the governance, failure analysis, and future-market test. While these components of the project were positioned more towards the end of the project, their development needed thorough understanding of the decisions made in the components prior to these. Therefore, our team supported a strong collaborative environment, where we discussed and reviewed many preceding stages as a group. The individual responsibility remained central, but within this we asked, brainstormed, and solved together. 

For the governance and failure analysis, I examined the potential failures of AI-based visual inspection. This included false acceptances and rejections, manipulated evidence, performance variation, and the limitations inherent to photographic assessment. I aimed to consider not only the identification of these potential failures, but additionally their consequences and the measures through which we could possibly mitigate them. Furthermore, I concerned myself with the future -market test. Here I examined how the proposed solution would remain strategically viable in an environment where other stakeholders, such as customers, suppliers, competitors and AI providers would also possess advanced AI capabilities. This required me to look beyond the immediate operational improvements, and consider how the technology might alter behaviour of other parties. 

2 Important Decisions and Iterations

If I could identify one of the major decisions we had to make during this project, it would be where the photographs used for inspection would originate. Initially, we considered photographing returned items in the warehouse, which would allow for relatively standardized photographic conditions and greater control over the evidence provided to our model. However, this also introduced additional operational costs, potentially undermining the very efficiency gains our solution intended to achieve. 

To mitigate this problem, we moved towards customer-submitted photographs. While this would solve the additional operation cost issue, it presented its own, new, problem: the consumer providing evidence also has an interest in the outcome of the assessment. The resulting information asymmetry became prominent in my failure analysis. Customers could potentially selectively photograph an item, conceal damages, or submit manipulated images. This led to the introduction of safeguards, such as live in-app photography, meta checks, and duplicate-image detection. However, this remains a limitation and can not entirely eliminate the underlying information asymmetry. Therefore, after iterating through the projects several stages we decided to implement the customer photography element and the decision was made to retain human oversight for uncertain or high-risk cases. 

3 Surprises & Failures

One of the most interesting realization was that the technological capabilities of the model did not necessarily constitute the primary obstacle to implementation. The difficulties often emerged when we attempted to translate those capabilities into a reliable and economically viable business process. 

Our evaluation demonstrated that the model could assess returned items considerably faster than human graders, averaging 5.9 seconds compared to approximately 38-48 seconds. Initially, this appeared promising. However, 50% of the evaluated cases were escalated for human review, whereas our economic analysis assumed an escalation rate of 20%. Although the evaluation sample deliberately included difficult cases and therefore hindered us from establishing the escalation rate under normal operating conditions, it raised an important concern. The economic viability of the system depends not merely on how quickly the AI can assess an item, but on how frequently its assessment actually replaces human labour. 

Another limitation became visible through the governance and failure analysis. Certain defects, such as changes in texture or internal damage cannot necessarily be observed through photographs. No matter how capable the model becomes, it cannot reliably identify information that the provided evidence does not contain. I found this distinction particularly important, as it demonstrates that not every limitation can be overcome through improved model performance. 

4 The Impact of feedback on Project Development

Feedback and discussion throughout the project were particularly useful in forcing us to reconsider assumptions that initially appeared relatively straightforward. Within my own contribution, this became apparent when examining the proposed mitigation measures. For example, requiring customers to take photographs directly through the application initially seemed like a reasonable response to manipulated evidence. However, further consideration revealed that photographs made live did not necessarily provide an accurate representation of an item’s condition. A customer could still deliberately omit particular angles without technically manipulating the image. Similarly, the discussion surrounding the visibility constraint made us reconsider what it actually meant if the model would make an error. We identified a distinction between incorrectly identifying an observable defect and being unable to assess a defect and being unable to assess a defect in the first place. The questions and feedback that the group provided on each member’s part, pushed the failure analysis away from general AI risks and towards more specific limitations. 

5 What was learned from the collaboration

Working in a group of four made the interdependence of the different project components particularly apparent. While the responsibilities could be divided relatively easily, the underlying assumptions and decisions could not be treated independently. For example, the economic analysis was dependent on assumptions regarding the proportion of cases requiring human intervention. The governance analysis introduced those safeguards that could then increase this proportion. A stricter approach to human oversight might improve decision reliability yet simultaneously reduce the expected cost savings. 

I found this particularly educational in the aspect of integrating different perspectives into one coherent business proposal. The collaboration therefore required more than combining individually completed sections. It demanded that we reconsidered how decisions made in one part of the project affected the arguments developed elsewhere. Looking back at it, I think this interdependence could have been addressed more explicitly throughout the development process, rather than primarily when bringing the separate components together. 

6 The Projects Influence on the Understanding of AI and Business Strategy

Before this project, I primarily associated the strategic value of AI with its ability to automate existing activities, thereby reducing costs and improving efficiency. This idea remains relevant, however, the project made me increasingly aware that the actual value of AI depends considerably more than the performance of the underlying model. Our model might predict that a returned item is in satisfactory condition, but it does not automatically mean that the retailer should approve the refund without further verification. And the decision also depends on how reliable the evidence is and what the consequences of an incorrect assessment are. I additionally came to realize that governance is not just an external constraint on technological innovation, but it also directly shapes its economic potential. Human oversight reduces the risk of incorrect decisions, but it also adds costs. So the strategic question isn’t just how much human involvement can be cut, but where it creates more value than if it were removed. My future-market analysis complicated things further. If Zara successfully implements AI-based return inspection, its competitors may introduce similar systems eventually. Meanwhile, customers equipped with their own AI tools may become better at navigating return policies, potentially creating new opportunities for strategic behaviour. So the competitive advantage cannot be assumed to come from just having an AI model. Instead, having proprietary return data, accumulated feedback, and integration into existing operations becomes more important.
Please rate this

From Reservations About AI → AI Reservations

9

October

2026

5/5 (1)

When I started the Information Strategy course, I had BIG reservations about AI. However, our AI Strategy Lab project, also linked to reservations, changed how I feel about AI in the end.

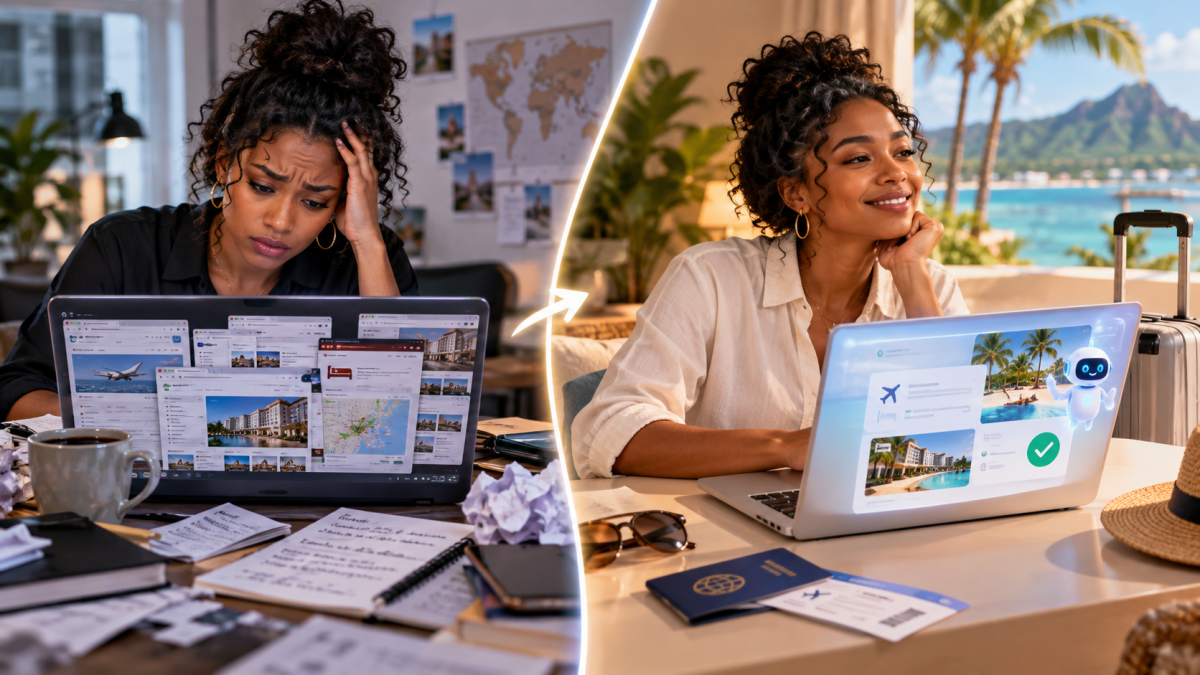
Planning and booking a trip can sometimes be annoying. What was meant to be an enjoyable process ends up becoming a frustrating one. Because you are busy jumping between websites, comparing flights and hotels, checking dates and cancellation policies and repeatedly entering the same information. I may have had reservations about AI, but the booking/reservation pains are enough to get me to be open about what AI can do.

Our travel idea was immediately interesting to me. However, I learned that relating to a problem personally does not automatically make it a good business opportunity. We still had to prove that the problem mattered beyond our own experiences and in which aspects AI added value.

We settled on Layla.ai as the business to focus on. I had never heard of Layla before and, honestly, wished I had. However, while we were looking into Layla, we found many flaws/processes that could be improved. Our initial idea was broad, including swipe-based discovery, personalised itineraries, and social travel. I liked the creativity of our initial idea, but it quickly became clear that we were trying to solve too many problems at once. Through iteration, we narrowed the idea to the gap between an approved itinerary and a completed booking. Rather than turning Layla into a different product, we proposed extending its existing planning capability so controlled Agentic AI could execute an already-approved itinerary.

A significant part of my contribution involved refining this problem and challenging whether we actually had evidence for it. At one stage, we considered statistics suggesting that around 82% of travel bookings were abandoned. We also found one customer review suggesting that a Layla booking had taken them a couple of weeks to complete. This review solidified why we proposed our solution, but it was just 1 customer review. Initially, both facts seemed useful because they supported the story we wanted to tell. However, one customer review could not represent Layla’s average booking experience, and the broader abondonment statistic did not prove that Layla itself had a conversion problem.

This made me realise how easy it is to start with a conclusion and then search for numbers that make it sound credible. We therefore looked for stronger evidence around customer effort, one-stop booking and digital friction. We stopped claiming that Layla had a proven conversion problem and instead argued that its planning-to-booking hand-off creates a plausible source of customer effort and potential transaction loss. One of my biggest lessons during this process was that a strategy can become stronger when you are willing to make a smaller, more defensible claim. Evidence should be able to challenge the idea, not simply support it.

We identified Layla as an Orchestrator because it coordinates different travel providers around what the traveller has approved rather than owning the underlying services. Layla was recently acquired by Expedia group so that gave it a more competitive stance as well against other incumbents like Booking.com. Applying concepts such as multihoming, price sensitivity, subsidy sides, and many sides also changed how I thought about pricing. Charging travellers an additional AI free when they already received free options from Layla itself could create friction exactly where we were trying to remove it, which led us towards a commission-funded model. At the same time, I learned that scalability and profitability are not the same. AI may reduce the cost of execution, but that does not mean every automated transaction created value.

The project also changed how I think about competitive advantage. Earlier, I saw Agentic AI itself as the differentiator. The future-market exercise challenged that assumption. If other OTAs and general AI assistants can eventually deploy capable agents, simply having an agent will not be much of a moat. For Layla, a more defensible position would need to come from traveller trust, supplier integration, reliable execution, and proprietary feedback loop learning. This taught me that technology can reshape competition without necessarily being the competitive advantage itself.

The prototype challenged another assumption that greater AI autonomy is automatically better. We developed a risk-weighted system in which human judgement increases with the consequences of the transaction. If a booking remains within agreed boundaries, the agent can do more. For example, if the price or itinerary changes materially, the traveller must approve again or the system should not only know how to act, but also when not to act.

When it comes to the general group assignment process, I found that collaboration was another important part of my learning. Towards the end of the assignment, I only realised then that sitting together and working on the project was much faster than everyone independently completing sections. We could challenge each other, identify inconsistencies, and make decisions immediately. Having worked professionally for more than seven years, I have high expectations around communication, presence, and shared responsibility. However, this also made me reflect on my own approach. I cannot assume that everyone shares my definition of good collaboration. In future projects, I would communicate expectations around availability and ways of working much earlier. Similar to how we discovered it, we cannot assume anything about AI/technology without figuring out its limitations first.

Looking back, my biggest takeaway is therefore not that AI is something to fear, nor that it should be used simply because it is available. AI strategy should begin with the problem rather than the technology. I started the project asking, “What can Agentic AI do?” and finished by asking much harder questions: Does this solve an important problem? Will customers delegate the task? Can the business capture enough value? What happens when competitors have the same capability? What could go wrong, and when should we stop rather than scale?

This is why our final recommendation was a controlled pilot rather than simply launching Agentic AI, just because it was technically possible. I still like the idea of making travel easier. Like being able to say, you know what I interact with on socials and what my Pinterest board looks like, plan my dream trip based on XXX budget and handle the annoying parts with the booking. What we presented is a starting point, to really amazing potential.

Turning frustration into a viable AI strategy requires more than a clever agent. It requires evidence, economics, trust, governance and a willingness to discover that your original idea might be wrong. The project ultimately moved me from fearing what AI might do, to thinking much more carefully about what we should allow it to do, and under what conditions.

Please rate this

FieldFinch – Project Learning Blog

9

October

2026

4/5 (1)

We created FieldFinch, an AI driven matchmaking platform that helps early-career researchers find the right expert beyond their own network: you describe the knowledge which your research requires and the platform provides experts from different fields with real publications as proof for every match.

My main contributions to the project were the problem & opportunity, the evaluation (simulation slide) and the second slide of the final recommendation in which we used the project findings to make decisions about what parts of the prototype to implement, change, test, scale or stop. These parts where closely connected. The problem & opportunity provided the initial explanation for why an AI driven academic matching platform could provide value, the simulation then tested if AI is capable of improving this matching process and the recommendation turned these results into practical next steps. Furthermore, I also contributed a lot to the overall consistency of the slideshow. I rewrote several parts to clarify certain parts of the project and adjusted the formatting and layouts so the slideshow looked like one coherent project.

The most difficult part of the project for me was deciding how we could meaningfully evaluate our concept, just claiming that AI would create better matches would not have provided convincing evidence. FieldFinch already had a prototype for the user interface but this did not prove if the AI matching functionality could actually perform the task that we had in mind. We also could not simply observe if researchers were finding useful experts through our platform without an existing user base. I therefore decided to test our claim with a small simulation which I had Claude run on OpenAlex data. The simulation used 5 academic collaborations from 2023 which were all written by two authors, each from a different field of research, who had also not worked together before. The simulation then picked one author as the “seeker” and solely searched for work published before 2023. Next, I checked if each search method found experts who were on-topic, if they were in the collaborator’s field and lastly if the real collaborator was found. The most important part of providing the evaluation was finding a meaningful baseline. Only using a simple keyword search in the “seeker’s” own words found zero on-topic experts, which would make our AI matching seem much more powerful. An informed keyword search using the terminology of an expert, however,  reached 68% on-topic against 84% on-topic for FieldFinch v1. After comparing FieldFinch to a fairer baseline we changed our claim, I had evidence that the AI was mostly useful for providing more reach, not relevance. This led me to the final conclusion that FieldFinch could find five times more experts from other fields than is currently possible through searching by keywords.

I learned most from the failures that the simulation produced. Claude built a second version of the simulation which split each research question into separate searches for the method and the field of research. Here I identified progress in the reach for cross-field research, which rose from 20% to 44%. Though the percentage of on-topic experts fell from 84% to 0%. For example, for one of the questions which was about patient no-shows, v2 suggested a paper on security in Java software. This is why I decided to keep v1, because having more reach without finding relevant research is quite useless for a researcher. Another failure was that no version of FieldFinch could find the real co-author of the paper in any of the five cases. The researchers earlier work was focused on general research methods, not the seeker’s specific problem which is why it never reached the top results. The data that we received also complicated our own problem statement. Several pairs of researchers we first looked at had already published together. This supports our claim that collaborations in scientific research are driven by existing networks and conversely shows that is very difficult for any matching tool to replace them. There were also some limitations to the simulation. Firstly, five cases is a very small sample size. Secondly, I let Claude run the entire simulation, including writing the search query. It wrote those queries with the real papers in mind which may have inflated the results of FieldFinch v1. That is why we eventually decided run a pilot with go/no-go targets instead of a full launch of the application.

Being responsible for both the evaluation and part of the recommendation made me see how evidence from the simulation changed our decisions. When writing the recommendation, I purposefully connected all decisions to a result from the simulation, so that the next steps would be based on real results instead of an opinion. Furthermore, I decided to implement FieldFinch v1 because it found a lot more cross-field experts at similar relevance. For the pilot launch, I made the choice that the tool should provide a source link for every claim that it makes to increase its trustworthiness and decided that the tool should match on whole expert profiles with embeddings, since it missed real co-authors in both v1 and v2. The evidence provided by the simulation also changed my assumption that AI would make finding experts much simpler. From v2, I could conclude that AI widens the search beyond a researcher’s own field, but it still misses expertise that can be transferred. I chose not to hide the weak result of the tool not matching 1 of the 5 cases with the co-author. Instead I used this as a reason to pilot FieldFinch at one research office first, with certain go/no-go targets.

The project taught me that during collaboration, dividing the work is the easy part. The hard part is making all those parts read as one project and making all those parts connect to be as convincing as possible. By rewriting sentences and changing the formatting I learned that the integration of individual work needs a clear owner, otherwise a project will end up looking uncoherent. If I would do the project again, I would assign the final round of proofreading and correcting as a separate task.

Starting out, I believed AI was a product on its own: you can give it an instruction and it matches people on its own. The project showed me, however, that there is much more to connecting the right people than just “letting AI match”. The instructions you give the AI tool decides a lot about the outcome, a small change in how v2 formulated the request changed relevant experts to irrelevant ones. It also made me aware that there are areas with clear limits to what AI can do, like matching junior researchers who do not have any publications yet. On the other hand, I was also very impressed by what AI could do, it ran our simulation and made a working prototype without writing any code ourselves. This made me realize that if we could make a protype this quickly, that competitors such as ResearchGate or Elsevier can create a similar matching tool with their existing userbase and data as well.

Please rate this

Project Learning Blog for Information Strategy

9

October

2026

No ratings yet.

For our AI Strategy Lab group project, our team developed “School IRL”, a concept designed to turn a student’s everyday surroundings into interactive learning moments. The core premise is straightforward: by pointing a standard smartphone camera at common physical objects—such as a bridge, a supermarket shelf, or a tree along the street—the application identifies the scene with computer vision and connects it directly to curriculum-aligned micro-lessons. Within our four-person team, my primary individual contributions centered on two foundational deliverables: Economics (cost structures, scalability, and pricing logic) and the Future-Market Test (assessing strategic resilience in an agent-dominated ecosystem).

My initial responsibility was building out the venture’s economic model. During our early ideation sessions, the team naturally fell into a conventional software mindset, assuming that once the application was built, serving additional students would incur virtually zero incremental expense. However, when I sat down to calculate the back-end unit economics of multimodal visual recognition and real-time lesson generation, reality hit hard. Modern vision-language models and generative outputs carry non-zero marginal inference costs. I ran a concrete baseline calculation: assuming an active student completes three neighborhood exploration quests a week and scans three to five items per quest, a single active user easily triggers dozens of multimodal API calls each month. If we offered unlimited free access to drive growth, our cloud compute bill would expand exponentially with user activity, destroying our unit economics from day one.

This cost realization marked our first critical pivot. It disproved our initial inclination toward a purely freemium consumer model and led me to restructure our monetization logic. I proposed that we shift to a B2B2C institutional model, packaging School IRL as a supplemental curriculum tool sold to schools and school districts through per-student annual SaaS licensing. For direct consumers, we introduced a capped monthly allowance of free scans, after which users purchase token packages. On the technical side, I also recommended caching common local objects—such as neighborhood landmarks, common trees, or standardized supermarket packaging—so the application serves pre-validated curriculum lessons instead of triggering expensive inference calls for identical items. This shifted our financial foundation from a vague traffic-first strategy to an operationally defensible business model.

My second major responsibility was executing the future-market test, which pushed us to evaluate how School IRL would survive if students, teachers, and competitors all had autonomous AI agents. Carrying out this simulation revealed a major vulnerability that nearly compromised our core value proposition. If every student soon has a capable multimodal AI agent running locally on their device, our planned learning loop—capturing an object, receiving questions, answering, and logging progress—becomes trivial to bypass. A student could point their camera, and their personal agent could intercept the prompt and generate correct answers in seconds, completely removing the student from the cognitive loop. If the software could not guarantee real student engagement, schools would have zero incentive to pay for it.

This failure analysis forced us to redesign our task format. We realized that trying to outsmart digital agents with text-based multiple-choice quizzes was pointless; our defensibility had to come from embodied, physical interaction in the real world. We restructured the lesson tasks to require situated observations that cannot be scraped from pure pixels. For instance, instead of asking an abstract economics question about supply and demand when looking at a supermarket shelf, the prompt requires the student to compare two specific packages of milk on the same shelf, calculate the price-per-liter difference on the spot, and enter that observed metric. When inspecting a bridge for physics, the task prompts the student to walk to the side support and observe the structural angle. By tying completion to physical observation, we raised the barrier against remote automated cheating and preserved the product’s instructional integrity.

Regarding our overall project scope, the team reached an early consensus: focus strictly on education, but avoid overcomplicated technologies. During initial brainstorms, we briefly discussed using immersive AR glasses or wearable sensors, but quickly dismissed them. In real educational environments, resource distribution is highly unequal; requiring specialized hardware would immediately price out underfunded public schools. Furthermore, advanced hardware creates steep training requirements for teachers, adding friction that stalls classroom adoption before it even begins. By deliberately choosing the smartphone already in a student’s pocket and focusing on common neighborhood objects, we ensured that any student within a short walk could access learning materials. This taught me that strategic competence is not about picking the most complex technology, but about achieving technology-tasks fit within real operational constraints.

From a collaboration standpoint, this project had an especially strong impact on me as an exchange student. In my home education background, learning is traditionally centered around lecture-based instruction, where teachers lecture from the front and students passively absorb notes. Coming from that setting, I had never considered how dynamic and contextualized learning could be simply by turning everyday street objects into interactive lessons through a smartphone. Working with team members from different backgrounds expanded my perspective on experiential and student-centered learning. This project was more than an academic exercise for credits; when I return home, I look forward to discussing these ideas with friends who teach, exploring how contextualized AI tools might reduce their lesson prep while making learning more engaging for students.

Overall, the AI Strategy Lab reshaped how I think about technology and management. I learned that developing a business strategy is never about presenting a flashy prototype; it requires calculating the underlying marginal compute costs, respecting operational constraints, and designing defenses against future technological shifts. This experience helped me step into the role of a strategic manager—one who uses economic principles and grounded judgment to turn technological capabilities into sustainable, real-world value.

Please rate this